

Browsing Tag
Ollama
9 posts
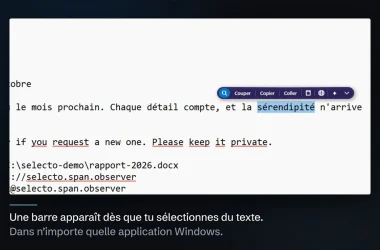
Translate selected text Windows AI with Selecto AI
Translate selected text Windows AI: Selecto AI, our free floating bar, translates, fixes and summarises with Ollama or your own keys.

Ollama vLLM llama.cpp: which local engine should you choose for LLMs?
Ollama vLLM llama.cpp: compare these three local inference engines by use case, hardware and monitoring (metrics, health checks, traces).
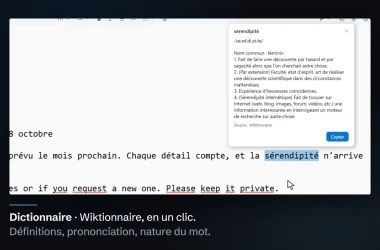
Selecto AI Windows: an action bar for any selected text
Selecto AI Windows adds an action bar to selected text: search, translate, summarise and correct with local Ollama AI or your own API key.
Open source LLM comparison: licence, size, VRAM and throughput measured on vLLM and Ollama
Open source LLM comparison: licence, parameters, GPU memory and Ollama tags for 8 verified models, plus a method to measure throughput on vLLM yourself.
ONLYOFFICE local AI with Ollama or vLLM: architecture, configuration and monitoring
ONLYOFFICE local AI: connect Docs 10.0 to Ollama or vLLM, tune aiSettings and the /ai-proxy relay, then monitor TTFT and StatsD with OpenTelemetry.
Self-hosted open source AI stack: comparing the building blocks of a self-hosted AI infrastructure
Compare the building blocks of a self-hosted open source AI stack: Ollama, vLLM, Open WebUI, LlamaIndex, CrewAI, Dify, n8n, Langfuse and typical setups.
LlamaIndex RAG on your internal documentation, and how to measure its quality
Build a self-hosted LlamaIndex RAG on your runbooks and procedures, then measure its quality: hit rate, MRR, faithfulness and relevancy of the answers.
Self-hosted Open WebUI: an internal ChatGPT in front of Ollama or an OpenAI-compatible API
Deploy self-hosted Open WebUI with Docker in front of Ollama or vLLM, secure it for a team, then trace every chat with OpenTelemetry through to the model.
Ollama local LLM: running models and monitoring them (metrics, logs, traces)
Ollama local LLM guide: install Ollama, serve a first model and monitor it with API probes, logs, GPU metrics and OpenTelemetry traces in Dynatrace.