


Browsing Tag
GPU
13 posts

Local MoE model: what Colibri asks of your disk
Local MoE model with Colibri: RAM, NVMe disk, published speeds and monitoring via /metrics. What the README says before you download 400 GB.

vLLM LLM inference: install and monitor the server
vLLM LLM inference, open source: install steps from the docs, architecture, service metrics (queue, KV cache, TTFT) and OpenTelemetry traces to watch.
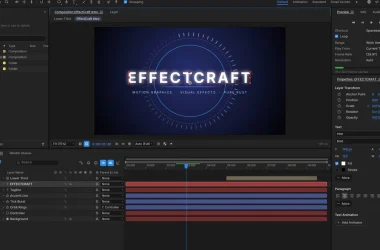
EffectCraft open source motion graphics: tour and limits
EffectCraft open source motion graphics in Rust: licence, screenshots, install steps from the README, alpha limits and what to measure on the workstation.
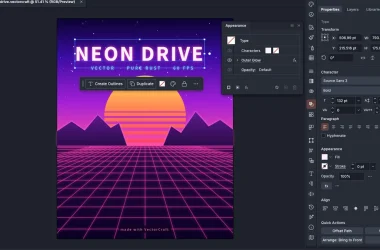
VectorCraft open source vector graphics editor: tour
VectorCraft open source vector graphics editor in Rust: licence, screenshots, install steps from the README, alpha limits and what to measure locally.
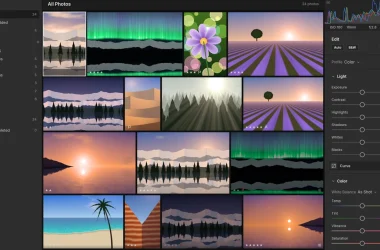
LightCraft non-destructive photo editor: tour and limits
LightCraft non-destructive photo editor in Rust: licence, screenshots, install steps from the README, alpha limits and what to measure on the workstation.
FilmCraft open source video editor in Rust: tour and limits
FilmCraft open source video editor in Rust: licence, screenshots, install steps from the README, alpha limits and what to measure on the workstation.
Open source LLM comparison: licence, size, VRAM and throughput measured on vLLM and Ollama
Open source LLM comparison: licence, parameters, GPU memory and Ollama tags for 8 verified models, plus a method to measure throughput on vLLM yourself.
Mistral Large 4 self-hosting: what is published, sizing and monitoring
Mistral Large 4 self-hosting: weights not yet released, memory to plan for 1 trillion parameters, and vLLM multi-GPU monitoring for operations teams.
Self-hosted open source AI stack: comparing the building blocks of a self-hosted AI infrastructure
Compare the building blocks of a self-hosted open source AI stack: Ollama, vLLM, Open WebUI, LlamaIndex, CrewAI, Dify, n8n, Langfuse and typical setups.
llama.cpp: local inference on CPU and GPU, GGUF models and the built-in HTTP server
Build llama.cpp, serve a GGUF model on CPU or GPU with the OpenAI-compatible llama-server, then monitor it: health checks, Prometheus metrics and logs.